Chorus

Chorus · free and open source

Hear what matters in the comments.

Map a video, see what people are talking about, and explore which comments a creator may answer.

Replyworthy runs on TabPFN-3.5 by Prior Labs.

  • Free open source
  • Local video and comment analysis
  • Optional Replyworthy

Replyworthy uses your own free Prior Labs account for live ranking. The saved demo needs no key.

Interactive illustration

Choose your reply threshold.

Synthetic comments. No API calls.

Compare each range with your threshold: at or above, Flag; crossing it, Check by hand; below it, Skip. No replies are posted.

Keyboard: arrows change 1%, Home jumps to 5%, End to 60%. Lanes settle when you pause or let go.

Flag 1

Whole range at or above your threshold

  1. C152%

    Synthetic comment: Could you test the same setup with less memory?

    Illustrative range 29% to 68%

    Question marks: 1 | Position 8 of 84 | Creator replies seen: 2 of 18

    Inspect C1
    Reply chance
    52%
    Range
    29% to 68%, an estimated reply rate for similar scores (illustrative)
    Fixed outcome
    Creator reply
    Source
    Authored fixture, not model output

    The inputs describe the row. They are not a proven cause of a reply.

Check by hand 2

Range crosses your threshold

  1. C239%

    Synthetic comment: At 03:12, is that the smaller model?

    Illustrative range 20% to 57%

    Question marks: 1 | Position 3 of 84 | Creator replies seen: 2 of 18

    Inspect C2
    Reply chance
    39%
    Range
    20% to 57%, an estimated reply rate for similar scores (illustrative)
    Fixed outcome
    No reply visible
    Source
    Authored fixture, not model output

    The inputs describe the row. They are not a proven cause of a reply.

  2. C328%

    Synthetic comment: Does the longer context change the result?

    Illustrative range 12% to 46%

    Question marks: 1 | Position 15 of 84 | Creator replies seen: 2 of 18

    Inspect C3
    Reply chance
    28%
    Range
    12% to 46%, an estimated reply rate for similar scores (illustrative)
    Fixed outcome
    No reply visible
    Source
    Authored fixture, not model output

    The inputs describe the row. They are not a proven cause of a reply.

Skip 9

Whole range below your threshold

  1. C44%

    Synthetic comment: Lovely work!

    Illustrative range 1% to 9%

    Question marks: 0 | Position 1 of 84 | Creator replies seen: 2 of 18

    Inspect C4
    Reply chance
    4%
    Range
    1% to 9%, an estimated reply rate for similar scores (illustrative)
    Fixed outcome
    No reply visible
    Source
    Authored fixture, not model output

    The inputs describe the row. They are not a proven cause of a reply.

  2. C53%

    Synthetic comment: The caption made me laugh.

    Illustrative range 1% to 7%

    Question marks: 0 | Position 22 of 84 | Creator replies seen: 2 of 18

    Inspect C5
    Reply chance
    3%
    Range
    1% to 7%, an estimated reply rate for similar scores (illustrative)
    Fixed outcome
    No reply visible
    Source
    Authored fixture, not model output

    The inputs describe the row. They are not a proven cause of a reply.

  3. C612%

    Synthetic comment: I tried this with a tiny test set.

    Illustrative range 4% to 24%

    Question marks: 0 | Position 5 of 84 | Creator replies seen: 2 of 18

    Inspect C6
    Reply chance
    12%
    Range
    4% to 24%, an estimated reply rate for similar scores (illustrative)
    Fixed outcome
    Creator reply
    Source
    Authored fixture, not model output

    The inputs describe the row. They are not a proven cause of a reply.

  4. C79%

    Synthetic comment: The side-by-side view helps.

    Illustrative range 3% to 18%

    Question marks: 0 | Position 31 of 84 | Creator replies seen: 2 of 18

    Inspect C7
    Reply chance
    9%
    Range
    3% to 18%, an estimated reply rate for similar scores (illustrative)
    Fixed outcome
    No reply visible
    Source
    Authored fixture, not model output

    The inputs describe the row. They are not a proven cause of a reply.

  5. C87%

    Synthetic comment: The second run was interesting.

    Illustrative range 2% to 14%

    Question marks: 0 | Position 40 of 84 | Creator replies seen: 2 of 18

    Inspect C8
    Reply chance
    7%
    Range
    2% to 14%, an estimated reply rate for similar scores (illustrative)
    Fixed outcome
    No reply visible
    Source
    Authored fixture, not model output

    The inputs describe the row. They are not a proven cause of a reply.

  6. C96%

    Synthetic comment: I use a similar setup.

    Illustrative range 2% to 13%

    Question marks: 0 | Position 12 of 84 | Creator replies seen: 2 of 18

    Inspect C9
    Reply chance
    6%
    Range
    2% to 13%, an estimated reply rate for similar scores (illustrative)
    Fixed outcome
    No reply visible
    Source
    Authored fixture, not model output

    The inputs describe the row. They are not a proven cause of a reply.

  7. C105%

    Synthetic comment: Saving this for the weekend.

    Illustrative range 1% to 11%

    Question marks: 0 | Position 57 of 84 | Creator replies seen: 2 of 18

    Inspect C10
    Reply chance
    5%
    Range
    1% to 11%, an estimated reply rate for similar scores (illustrative)
    Fixed outcome
    No reply visible
    Source
    Authored fixture, not model output

    The inputs describe the row. They are not a proven cause of a reply.

  8. C112%

    Synthetic comment: A neat little experiment.

    Illustrative range 0% to 6%

    Question marks: 0 | Position 63 of 84 | Creator replies seen: 2 of 18

    Inspect C11
    Reply chance
    2%
    Range
    0% to 6%, an estimated reply rate for similar scores (illustrative)
    Fixed outcome
    No reply visible
    Source
    Authored fixture, not model output

    The inputs describe the row. They are not a proven cause of a reply.

  9. C121%

    Synthetic comment: Thanks for sharing the test.

    Illustrative range 0% to 4%

    Question marks: 0 | Position 70 of 84 | Creator replies seen: 2 of 18

    Inspect C12
    Reply chance
    1%
    Range
    0% to 4%, an estimated reply rate for similar scores (illustrative)
    Fixed outcome
    No reply visible
    Source
    Authored fixture, not model output

    The inputs describe the row. They are not a proven cause of a reply.

Totals

Flag
1
Check by hand
2
Skip
9
Decided coverage
83% (10/12)
Errors / decided
1/10

Counts over twelve invented comments with fixed invented outcomes. Illustrative, not measured accuracy.

Illustrative, not measured. Twelve invented comments, scores, ranges and outcomes. These are not TabPFN predictions. Scores and ranges stay fixed when the threshold moves.
Results · TabPFN-3.5 Hackathon entry

What TabPFN-3.5 does for Replyworthy

Tested on 169,002 comments from 384 channels in the curator's own AI playlist (so the choice of videos reflects one person's interests; none of their viewing data is used), 11.9% of them answered by the creator. Two test sets: the later comments of known channels (25,517 comments, 8.3% answered) and 58 channels never used for training (16,584 comments, 14.3% answered). The numbers below are measured results, unlike the demo above.

Chances a creator can read as chances

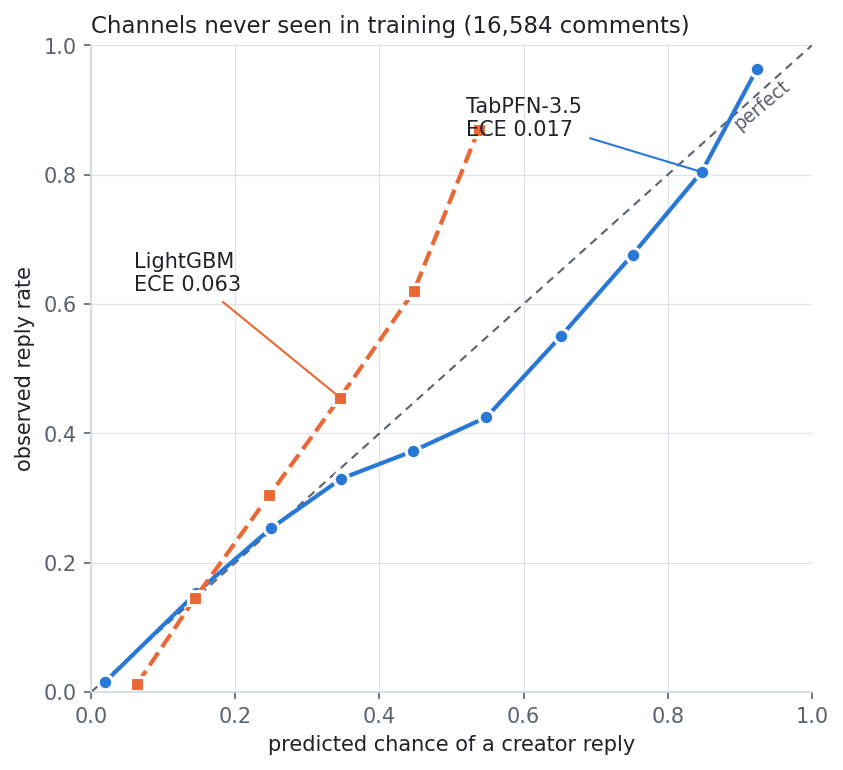
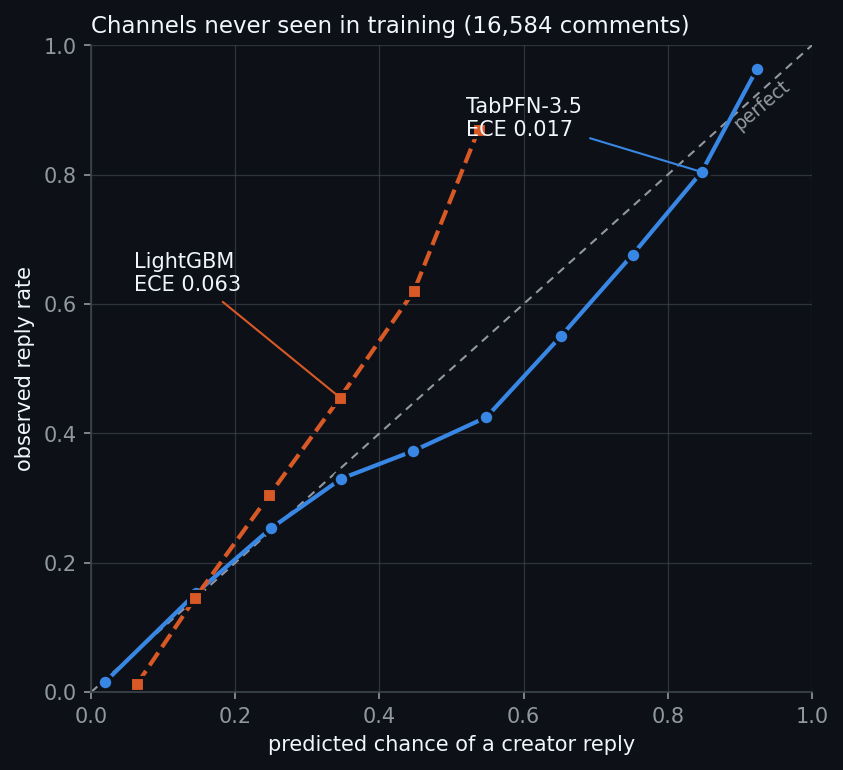
On channels it has never seen, TabPFN-3.5's predicted chances stay close to what happened: calibration error (ECE) 0.017, against 0.063 for LightGBM and 0.089 for XGBoost. It also has the lower Brier score; the 95% bootstrap interval of the difference against LightGBM is -0.014 to -0.004, resampling whole videos.

Reliability on channels never seen in training: TabPFN-3.5 follows the diagonal (ECE 0.017); LightGBM predicts too low, for example 54% where 87% were answered (ECE 0.063). Reliability on channels never seen in training: TabPFN-3.5 follows the diagonal (ECE 0.017); LightGBM predicts too low, for example 54% where 87% were answered (ECE 0.063).
Reliability on unseen channels. Lower ECE is better.

Skip, check by hand, flag

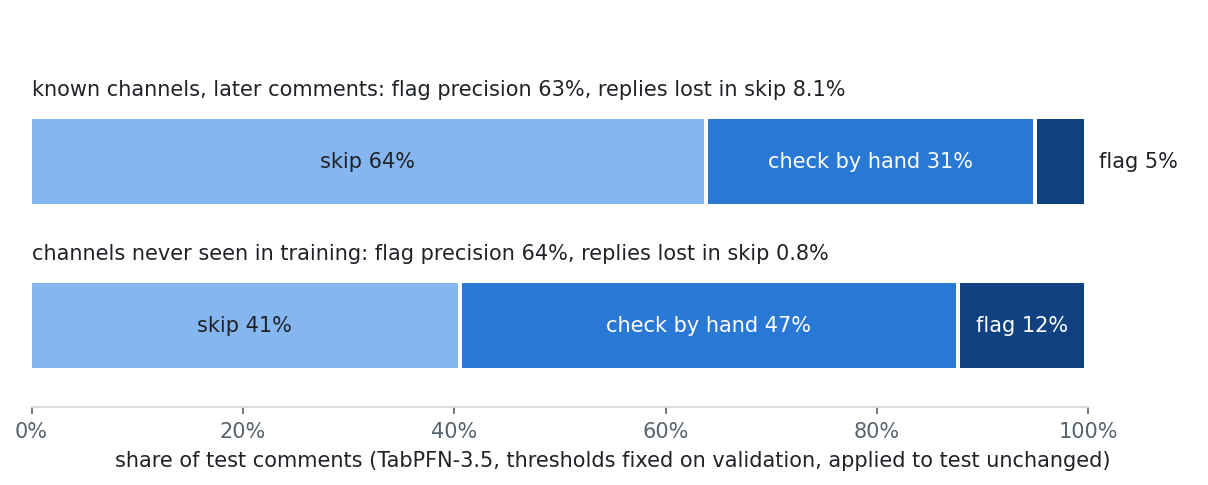
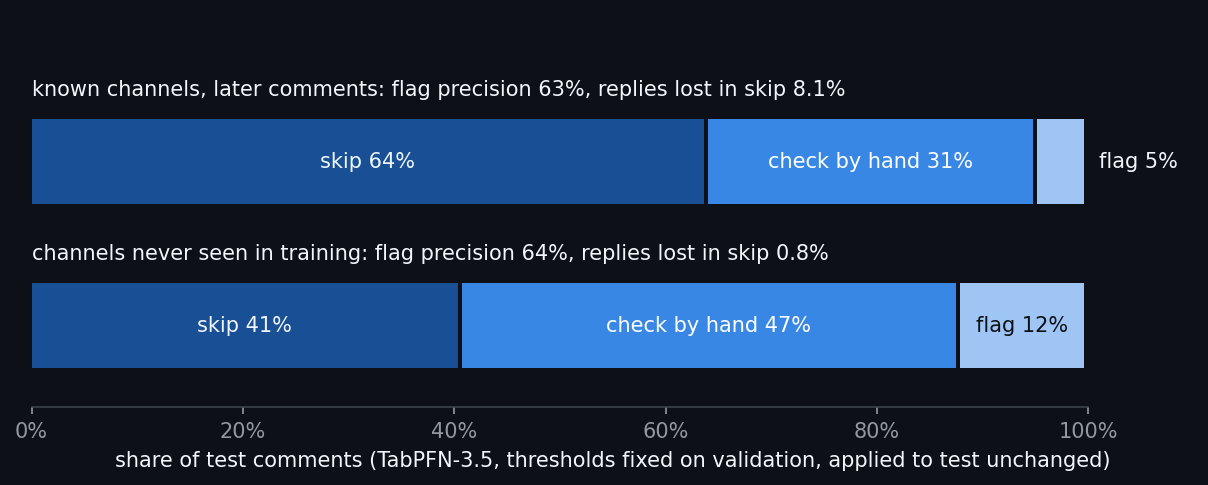
Calibrated chances make three zones work. Thresholds are fixed on validation data and applied to test unchanged. On known channels a creator can skip 64% of comments and lose 8.1% of the replies they would have made; the 4.8% flagged are answered 62.6% of the time and hold 36.4% of all replies. On new channels the flag holds 54.7% of the replies at 64.5% precision, and skip loses 0.8%.

Skip, check and flag shares on test. Known channels: skip 64%, check 31%, flag 5%. New channels: skip 41%, check 47%, flag 12%. Skip, check and flag shares on test. Known channels: skip 64%, check 31%, flag 5%. New channels: skip 41%, check 47%, flag 12%.
Share of test comments in each zone.

Cold start: a new channel, a few labels, no retraining

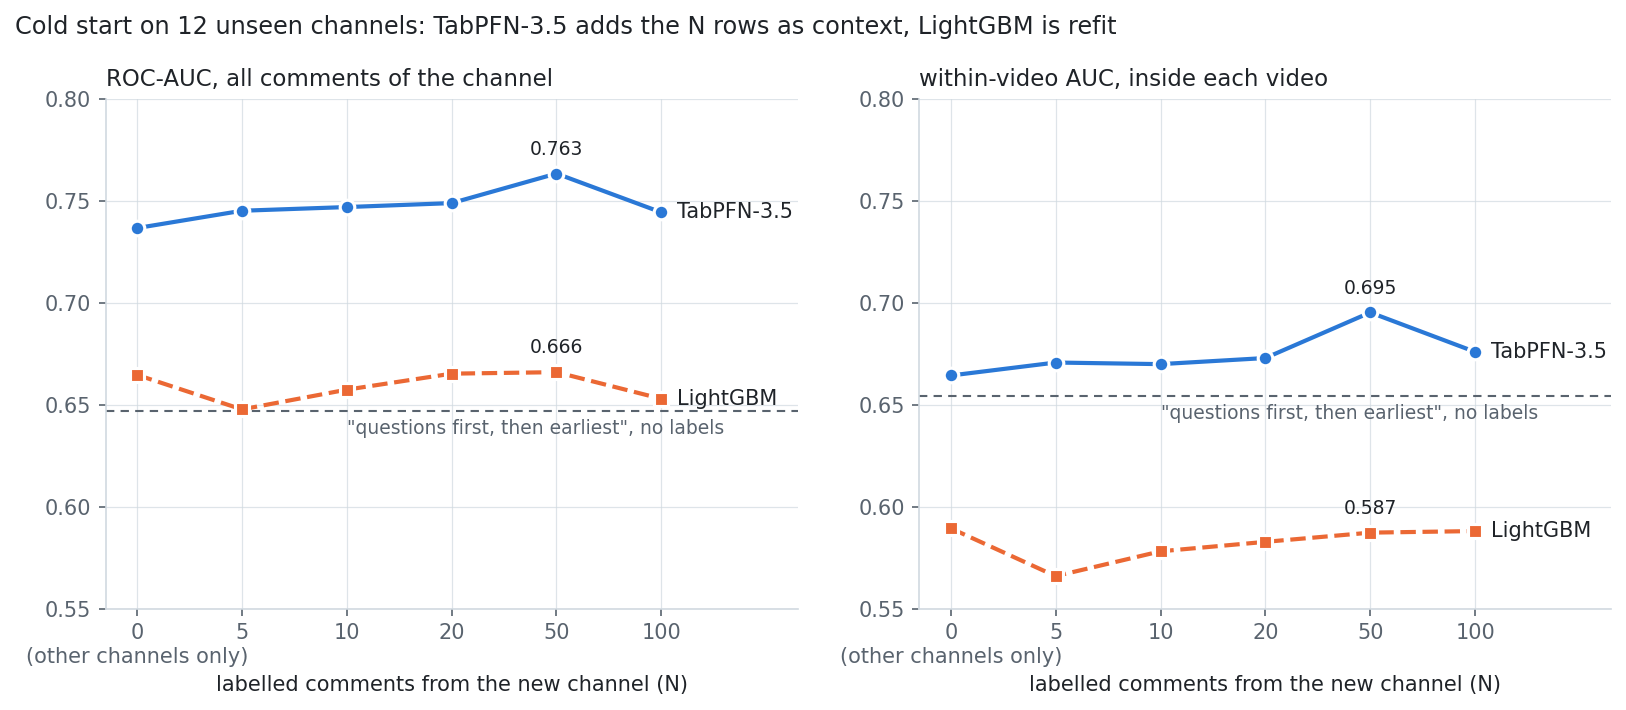
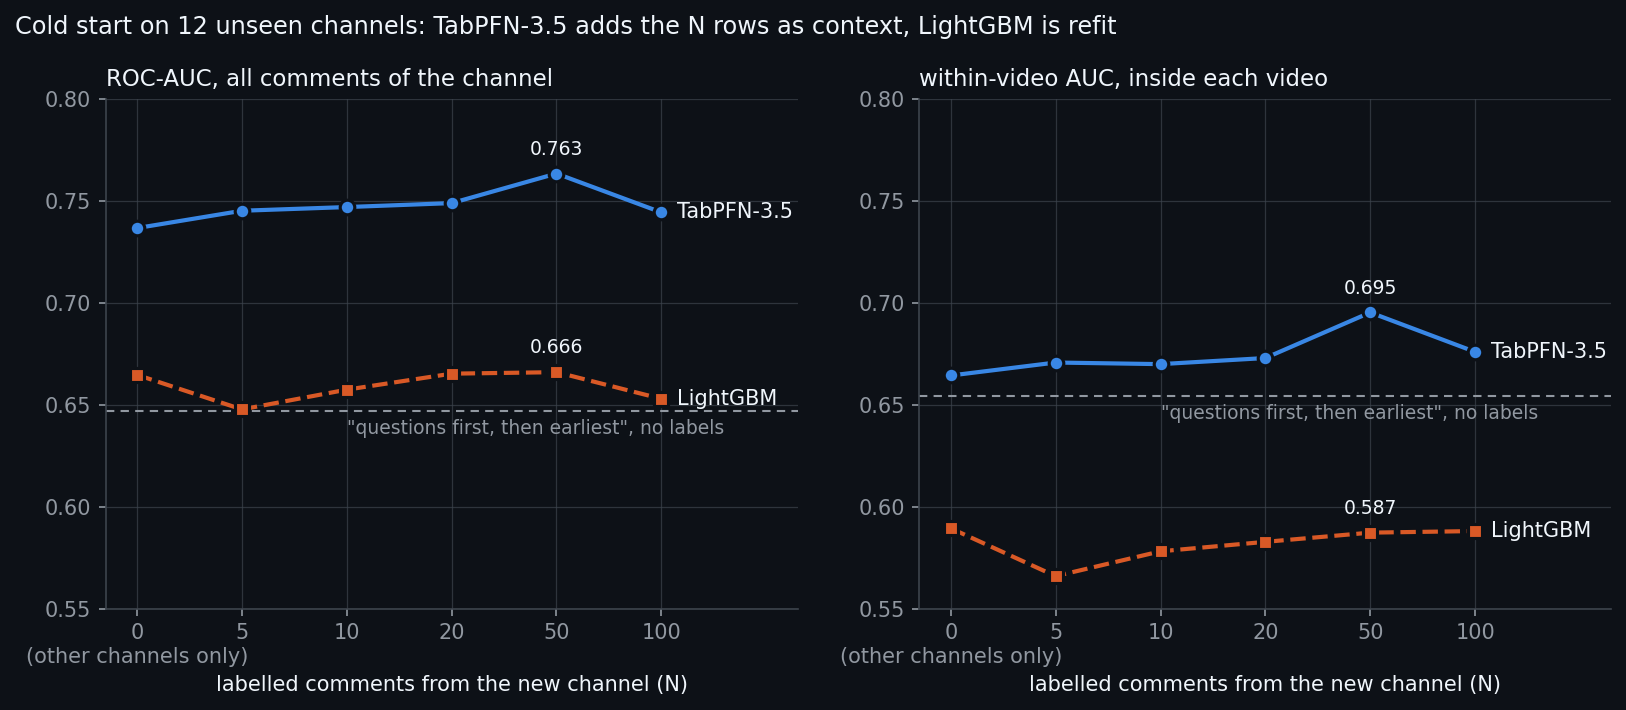
For 12 channels never seen in training, TabPFN-3.5 gets the other channels' comments plus the new channel's first N labelled comments as context; LightGBM is refit on the same rows. TabPFN-3.5 leads at every N from 0 to 100: ROC-AUC 0.737 to 0.763 against 0.648 to 0.666, and within-video AUC 0.664 to 0.695 against 0.566 to 0.589. The curve is not steady (N = 100 falls back to 0.744), so the robust result is the lead itself; the extra gain from a channel's own labels is small.

Cold start on 12 unseen channels. TabPFN-3.5 with other channels plus N labelled comments: ROC-AUC from 0.737 at N=0 to 0.763 at N=50; within-video AUC 0.664 to 0.695. LightGBM refit: 0.665 to 0.666 and 0.589 to 0.587. Cold start on 12 unseen channels. TabPFN-3.5 with other channels plus N labelled comments: ROC-AUC from 0.737 at N=0 to 0.763 at N=50; within-video AUC 0.664 to 0.695. LightGBM refit: 0.665 to 0.666 and 0.589 to 0.587.
Cold start on 12 unseen channels, by number of labelled comments N.

Fast enough for a watch page

With a channel's history cached on the Prior Labs server (median 7,834 context rows), ranking a new video's comments (median 283) takes 0.65 s of server time and 1.3 s wall clock, against 2.3 s uncached. Building the cache costs about 9 s once per channel. The whole Day 2 study used 1,787,501 of the 20 million free monthly API tokens.

What it does not win

  • Ranking inside one video. On new channels, a LightGBM ranker trained per video orders a video's comments best: within-video AUC 0.741 against 0.641 for TabPFN-3.5. On known channels TabPFN-3.5 (0.658), the ranker (0.655) and the rule "questions first, then earliest" (0.645) are close.
  • Thinking mode. PR-AUC changed by -0.002 (known) and -0.004 (new channels), inside the bootstrap interval, for about twice the tokens.
  • Reading the text is not enough. An LLM that read 400 test comments ranked them no better than the channel's past reply rate (PR-AUC 0.174 against 0.189).

Source: results/tabpfn_v1.md and results/llm_judge_v1.md. The per-comment data is not published (it derives from YouTube API data); the code, the method and a synthetic stand-in are.

How we built it

We started by listening.

  1. A codebook from the comments

    Open coding showed that many comments are about the creator or the video, and bare reactions often have no topic. Two independent AI coders on 100 held-back comments agreed at kappa 0.96 on the main theme.

  2. The best global score was not the best video ranking

    Trees led on PR-AUC across videos, but inside one video they ranked no better than "questions first, then earliest". We now report within-video ranking next to PR-AUC.

  3. A port, not a redesign

    The extension reuses a working watch page, keeps comment text in the browser, and shows a range next to every chance.

  4. What TabPFN-3.5 is good at

    Honest probabilities and a fast cold start on new channels; not the ranking inside one video.

Read the full evolution log

Install and begin

Get the preview build

No Chorus account. No key for local analysis or saved demos. Live Replyworthy is optional.

  1. Get the source and the unpacked Chrome extension from the repository.
  2. Open a YouTube watch page. Quick signals work straight away.
  3. Optional: add your own free Prior Labs key for live Replyworthy ranking.

There is no Chrome Web Store listing yet. The preview is installed from source.